牛仔行头目标检测竞赛 李沐老师Kaggle(有代码有注释)
)
一、比赛地址
CowBoy Outfits Detection | Kaggle
二、数据介绍
这次比赛的数据集一共有4879个image,需要自己划分训练集和验证集。annotation的格式是json,因此如果用yolo系列的算法会涉及到json2txt这一步。当然如果不用yolo系列的就不要这段代码了。本文使用的是yolov5,所以文章内有json2txt的代码
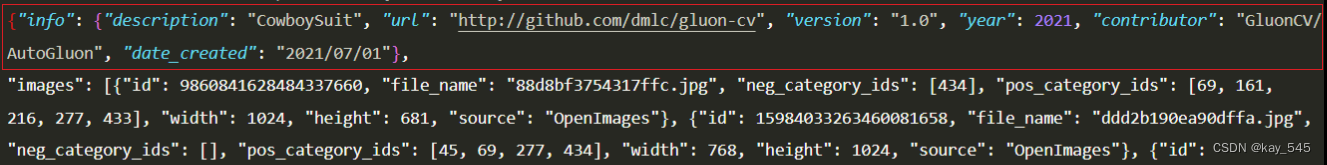
json里面是一个大的字典,里面有三个键值对。第一个key是info,这个是描述的数据集信息,第二个image,里面有一些图片的文件名称之类的,如下图所示,最后一个key是annotation,里面有被标记的物体的坐标,xywh等一些关键信息。这个json文件比较特殊,annotation和img对应上需要id对应,而不是文件名,在image里面的id和annotation的image_id是能够匹配上的关键信息。
接下来我就来处理这些数据
三、代码,注释
第一步当然是导包了
import os
import json
import yaml
import pandas as pd
import shutil
import random
第二步是加载数据
data =json.load(open(r"D:\cowboyoutfits\\train.json", 'r'))
label = data['annotations'] # 这个就是把json文件里的annotations提取出来了
# print(label)
random.seed(34) # 随机种子的作用是为了固定每次被随机采样的img,在划分train和val用
random.shuffle(label) #打乱标签
第三步是print一下每个类别的数量,以便确定valset里面的每个类别的数量
ci = [87,1034,131,318,588]  #这个数据是从json文件中获得的,就是category_id
print('total:') # 打印每个类别的总数,每个类别对应一个数据
for i in ci:count = 0  # 注意count的位置,我上次leetcode刷题放错位置了,导致一直输出0for j in label:if j['category_id'] == i:count +=1print(f'id:{i} counts:{count}')
第四步
print是你的好朋友,在看不懂的时候需要print,也需要print(type())
total_id = set(each['image_id'] for each in label ) # 比较复杂,for循环获取每个label中的字典,label的类型是string,里面包含的是dict,然后在获取image_id,转化为集合
# print(len(total_id))
# print(total_id)
第五步,这一步是找出符合要求的图片作为valset
val_id = set()  # total_id用的集合,这里也用集合,可以保证唯一性
a, b, c, d, e = 0, 0, 0, 0, 0
# val的数量少于50=2+20+4+7+17
for each in label:if (each['category_id'] == ci[0] ) and (a < 2):val_id.add(each['image_id'])  # 集合的属性,add,list属性是appenda +=1  # 这一步是处理图片elif (each['category_id'] == ci[1]) and (b < 20):val_id.add(each['image_id'])b +=1elif (each['category_id'] == ci[2]) and (c < 4):val_id.add(each['image_id'])c +=1elif (each['category_id'] == ci[3]) and (d < 7):val_id.add(each['image_id'])d +=1elif (each['category_id'] == ci[4]) and (e < 17):val_id.add(each['image_id'])e +=1
第六步,valset的img已经找到,现在需要找出对应的annotation,下面的算法,有一个复杂度是n^2,想不到复杂度更低的,如果大家能想出来,欢迎大家踊跃评论。
# 先通过种类找出image_id,再通过image_id找出annotations
# val_ann = [each_ann for each_ann in label if each_ann['image_id'] in val_id] # 这个也不快,还难懂
val_ann = []  # 开始处理annotations
for imid in val_id: # 这样处理其实很慢的,复杂度是n*m,不过数量比较少,实际有用的结果只有n(相等时)for each_ann in label:if each_ann['image_id'] == imid:val_ann.append(each_ann) # list appendprint(len(val_id),len(val_ann))
# 50, 177
#不一样是因为有的一张图片有多个object
第七步,打印valset的总框数
print('val_set')for kind in ci:num = 0for i in val_ann:if i['category_id'] == kind:num += 1 print(f'id: {kind} counts: {num}') # 这个应该是物体的数量,总框数第八步,总的数据集减去valset,就是trainset
train_id = total_id - val_id # 这个是集合的减法
# print(train_id = total_id - val_id)
train_ann = []
for each_ann in label:for tid in train_id:  if each_ann['image_id'] == tid:train_ann.append(each_ann)break # 找到就退出内层循环,去掉break会得到重复的结果  for循环换一下就能省掉break了,因为tid是唯一的,each_ann可能是多个
print(len(train_id),len(train_ann))  # 标签和照片数量不等是因为每个照片可能有多个标签
第九步,创建文件夹,将图片放进对应的文件夹中
file_path = "D://cowboyoutfits//images//"
# print(os.path.join(file_path,'train'))
os.makedirs(os.path.join(file_path,'train'),exist_ok= True) # 在路径下创建文件夹
os.makedirs(os.path.join(file_path,'val'),exist_ok= True)# current_path = os.getcwd()
# print("当前路径是:", current_path)train_img = []
for j in data['images']:for i in train_id:if j['id'] == i:shutil.copy(file_path + j['file_name'],"D:\\cowboyoutfits\\images\\train") #两个参数,第一个是原来的文件,即目标文件,第二个参数是要复制到的文件夹 # 使用os.path.splitext获取文件名和后缀# file_name, file_extension = os.path.splitext(os.path.basename(file_path))# 扩展不要可以 file_name, _ = os.path.splitext(os.path.basename(file_path))# 扩展不要可以 file_name= os.path.splitext(file_path)[0])train_img.append(j)val_img = []
for j in data['images']:for i in val_id:if j['id'] == i:shutil.copy(file_path + j['file_name'],"D:\\cowboyoutfits\\images\\val")val_img.append(j)print(len(val_img),len(train_img))
第十步,将annotation放到对应的文件夹下,并将json2txt
os.makedirs(os.path.join(file_path,'labels','train'), exist_ok=True)
os.makedirs(os.path.join(file_path,'labels','val'), exist_ok=True)train_info = [(each['id'], each['file_name'].split('.')[0], each['width'], each['height']) for each in train_img]
val_info = [(each['id'], each['file_name'].split('.')[0], each['width'], each['height']) for each in val_img]trans = {f'{each}':f'{idx}' for (idx,each) in enumerate(ci)} # 转化为字典,type(trans)--dict# trans = dict(zip(ci,range(len(ci)))) #不一样,没引号# Create *.txt files for training
for (imid,fn,w,h) in train_info:with open ('D:\\cowboyoutfits\\images\\labels\\train\\' + fn + '.txt', 'w') as t_f:for t_ann in train_ann:if t_ann['image_id'] == imid:bbox = [str((t_ann['bbox'][0] + (t_ann['bbox'][2] / 2) - 1) / float(w)) + ' ', # 计算 x 中心坐标,并进行归一化。str((t_ann['bbox'][1] + (t_ann['bbox'][3] / 2) - 1 )/ float(h)) + ' ',str(t_ann['bbox'][2] / float(w)) + ' ',  # 计算宽度,并进行归一化。str(t_ann['bbox'][3] / float(h))]print(bbox)t_f.write(trans[str(t_ann['category_id'])] + ' ' + str(bbox[0] + bbox[1] + bbox[2] + bbox[3]))t_f.write('\n')# Create *.txt files for evaluating
for (imid, fn, w, h) in val_info:with open('D:\\cowboyoutfits\\images\\labels\\val\\' + fn + '.txt', 'w') as v_f:for v_ann in val_ann:if v_ann['image_id'] == imid:bbox = [str((v_ann['bbox'][0] + (v_ann['bbox'][2] / 2) - 1) / float(w)) + ' ',str((v_ann['bbox'][1] + (v_ann['bbox'][3] / 2) - 1) / float(h)) + ' ',str(v_ann['bbox'][2] / float(w)) + ' ',str(v_ann['bbox'][3] / float(h))]v_f.write(trans[str(v_ann['category_id'])] + ' ' + str(bbox[0] + bbox[1] + bbox[2] + bbox[3]))v_f.write('\n')
第十一步,设定一些参数,数据集放置的路径等生成yaml文件
data_yaml = dict(path = 'D:/cowboyoutfits', # dataset toot dirtrain = 'images/train', # train images('relative to 'path')val = 'images/val', # val images (relative to 'path')test = 'images/test', # test images (relation to 'path')nc = 5,names = ['belt', 'sunglasses', 'boot', 'coeboy_hot', 'jacket'],download = 'None'  )
with open('D:/cowboyoutfits/my_data_config.yaml', 'w') as f:yaml.dump(data_yaml, f, default_flow_style=False)hyp_yaml = dict(lr0 = 0.01, # initial learning rate (SGD=1E-2,Adam=1E-3)lrf = 0.16, # final OneCycleLR learning rate (lr0 * lrf)momentum = 0.937, # SGD momentum/Adam beta1weight_decay = 0.0005, # optimizer weight decay 5e-4warmup_epoch = 5.0, # warmup epochs(fractions ok)warmup_momentum = 0.8, # warmup initial momentumwarmup_bias_ls = 0.1, # warmup initial bias lr  box = 0.05, # box loss gain cls = 0.3, # cls loss gaincls_pw = 1.0, # cls BECloss positive_weightobj = 0.7, #obj loss gain (scale with pixels)obj_pw = 1.0, # obj BCELoss positive_weightiou_t = 0.20, #IoU training thresholdanchor_t =  4.0, # anchor-multiple thredsholdfl_gamma = 0.0, # focal loss gamma (efficientDet default gamma= 1.5)hsv_h = 0.015, # images HSV-Hue augmentation (fraction)hsv_s = 0.7, # images HSV-Saturation augmentation (fraction)hsv_v = 0.4, # images HSV-Value augmentation (fraction)degrees = 0.0, #images rotatio(+/- deg)translate = 0.1, # images translation (+/- fraction)scale = 0.25, # image scale(+/- gain)shear = 0.0, # image shear(+/- deg)perspective = 0.0, # image perspective (+/- fraction), range 0-0.001flipup = 0.0, # image flip up-down(probability)fliplr = 0.5, # image flip left-right(probability)mosaic = 1.0, # image mosaic(probability)mixup = 0.0, # image mixup (probability)copy_paste = 0.0, # segment copy-paste (probability)  )with open('D:/cowboyoutfits/hyp_config.yaml','w') as f:yaml.dump(hyp_yaml, f, default_flow_style=False)
第十二步,调用yolov5的三个模型。有两个使用了transformer,transformer也可以多加层,只不过我电脑不太行,只能加这点。没在服务器上运,大家有条件的可以试试。
model1_yaml = dict(nc = 5,  # number of classesdepth_multiple = 1.33,  # model depth multiplewidth_multiple = 1.25,  # layer channel multipleanchors = 3,  # 这里把默认的anchors配置改成了3以启用autoanchor, 获取针对自己训练时的img_size的更优质的anchor size# YOLOv5 backbonebackbone =# [from, number, module, args][[-1, 1, 'Focus', [64, 3]],  # 0-P1/2[-1, 1, 'Conv', [128, 3, 2]],  # 1-P2/4[-1, 3, 'C3', [128]],[-1, 1, 'Conv', [256, 3, 2]],  # 3-P3/8[-1, 9, 'C3', [256]],[-1, 1, 'Conv', [512, 3, 2]],  # 5-P4/16[-1, 9, 'C3', [512]],[-1, 1, 'Conv', [768, 3, 2]],  # 7-P5/32[-1, 3, 'C3', [768]],[-1, 1, 'Conv', [1024, 3, 2]],  # 9-P6/64[-1, 1, 'SPP', [1024, [3, 5, 7]]],[-1, 3, 'C3', [1024, 'False']],  # 11],# YOLOv5 headhead =[[-1, 1, 'Conv', [768, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 8], 1, 'Concat', [1]],  # cat backbone P5[-1, 3, 'C3', [768, 'False']],  # 15[-1, 1, 'Conv', [512, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 6], 1, 'Concat', [1]],  # cat backbone P4[-1, 3, 'C3', [512, 'False']],  # 19[-1, 1, 'Conv', [256, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 4], 1, 'Concat', [1]],  # cat backbone P3[-1, 3, 'C3', [256, 'False']],  # 23 (P3/8-small)[-1, 1, 'Conv', [256, 3, 2]],[[-1, 20], 1, 'Concat', [1]],  # cat head P4[-1, 3, 'C3', [512, 'False']],  # 26 (P4/16-medium)[-1, 1, 'Conv', [512, 3, 2]],[[-1, 16], 1, 'Concat', [1]],  # cat head P5[-1, 3, 'C3', [768, 'False']],  # 29 (P5/32-large)[-1, 1, 'Conv', [768, 3, 2]],[[-1, 12], 1, 'Concat', [1]],  # cat head P6[-1, 3, 'C3', [1024, 'False']],  # 32 (P6/64-xlarge)[[23, 26, 29, 32], 1, 'Detect', ['nc', 'anchors']],  # Detect(P3, P4, P5, P6)])
with open('D:/cowboyoutfits/yolov5x6.yaml', 'w') as f:yaml.dump(model1_yaml, f, default_flow_style=True)model2_yaml = dict(nc = 5,  # number of classesdepth_multiple = 1.33,  # model depth multiplewidth_multiple = 1.25,  # layer channel multipleanchors = 3,  # 这里把默认的anchors配置改成了3以启用autoanchor, 获取针对自己训练时的img_size的更优质的anchor size# YOLOv5 backbonebackbone =# [from, number, module, args][[-1, 1, 'Focus', [64, 3]],  # 0-P1/2[-1, 1, 'Conv', [128, 3, 2]],  # 1-P2/4[-1, 3, 'C3', [128]],[-1, 1, 'Conv', [256, 3, 2]],  # 3-P3/8[-1, 9, 'C3', [256]],[-1, 1, 'Conv', [512, 3, 2]],  # 5-P4/16[-1, 9, 'C3', [512]],[-1, 1, 'Conv', [768, 3, 2]],  # 7-P5/32[-1, 3, 'C3', [768]],[-1, 1, 'Conv', [1024, 3, 2]],  # 9-P6/64[-1, 1, 'SPP', [1024, [3, 5, 7]]],[-1, 3, 'C3TR', [1024, 'False']],  # 11  <-------- C3TR() Transformer module],# YOLOv5 headhead =[[-1, 1, 'Conv', [768, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 8], 1, 'Concat', [1]],  # cat backbone P5[-1, 3, 'C3', [768, 'False']],  # 15[-1, 1, 'Conv', [512, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 6], 1, 'Concat', [1]],  # cat backbone P4[-1, 3, 'C3', [512, 'False']],  # 19[-1, 1, 'Conv', [256, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 4], 1, 'Concat', [1]],  # cat backbone P3[-1, 3, 'C3', [256, 'False']],  # 23 (P3/8-small)[-1, 1, 'Conv', [256, 3, 2]],[[-1, 20], 1, 'Concat', [1]],  # cat head P4[-1, 3, 'C3', [512, 'False']],  # 26 (P4/16-medium)[-1, 1, 'Conv', [512, 3, 2]],[[-1, 16], 1, 'Concat', [1]],  # cat head P5[-1, 3, 'C3', [768, 'False']],  # 29 (P5/32-large)[-1, 1, 'Conv', [768, 3, 2]],[[-1, 12], 1, 'Concat', [1]],  # cat head P6[-1, 3, 'C3', [1024, 'False']],  # 32 (P6/64-xlarge)[[23, 26, 29, 32], 1, 'Detect', ['nc', 'anchors']],  # Detect(P3, P4, P5, P6)])
with open('D:/cowboyoutfits/yolov5x6-transformer.yaml', 'w') as f:yaml.dump(model2_yaml, f, default_flow_style=True)model3_yaml = dict(nc = 5,  # number of classesdepth_multiple = 1.0,  # model depth multiplewidth_multiple = 1.0,  # layer channel multipleanchors = 3,  # 这里把默认的anchors配置改成了3以启用autoanchor, 获取针对自己训练时的img_size的更优质的anchor size# YOLOv5 backbonebackbone =# [from, number, module, args][[-1, 1, 'Focus', [64, 3]],  # 0-P1/2[-1, 1, 'Conv', [128, 3, 2]],  # 1-P2/4[-1, 3, 'C3', [128]],[-1, 1, 'Conv', [256, 3, 2]],  # 3-P3/8[-1, 9, 'C3', [256]],[-1, 1, 'Conv', [512, 3, 2]],  # 5-P4/16[-1, 9, 'C3TR', [512]],  #   <-------- C3TR() Transformer module[-1, 1, 'Conv', [768, 3, 2]],  # 7-P5/32[-1, 3, 'C3', [768]],[-1, 1, 'Conv', [1024, 3, 2]],  # 9-P6/64[-1, 1, 'SPP', [1024, [3, 5, 7]]],[-1, 3, 'C3TR', [1024, 'False']],  # 11  <-------- C3TR() Transformer module],# YOLOv5 headhead =[[-1, 1, 'Conv', [768, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 8], 1, 'Concat', [1]],  # cat backbone P5[-1, 3, 'C3', [768, 'False']],  # 15[-1, 1, 'Conv', [512, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 6], 1, 'Concat', [1]],  # cat backbone P4[-1, 3, 'C3', [512, 'False']],  # 19[-1, 1, 'Conv', [256, 1, 1]],[-1, 1, 'nn.Upsample', ['None', 2, 'nearest']],[[-1, 4], 1, 'Concat', [1]],  # cat backbone P3[-1, 3, 'C3', [256, 'False']],  # 23 (P3/8-small)[-1, 1, 'Conv', [256, 3, 2]],[[-1, 20], 1, 'Concat', [1]],  # cat head P4[-1, 3, 'C3', [512, 'False']],  # 26 (P4/16-medium)[-1, 1, 'Conv', [512, 3, 2]],[[-1, 16], 1, 'Concat', [1]],  # cat head P5[-1, 3, 'C3', [768, 'False']],  # 29 (P5/32-large)[-1, 1, 'Conv', [768, 3, 2]],[[-1, 12], 1, 'Concat', [1]],  # cat head P6[-1, 3, 'C3', [1024, 'False']],  # 32 (P6/64-xlarge)[[23, 26, 29, 32], 1, 'Detect', ['nc', 'anchors']],  # Detect(P3, P4, P5, P6)],)
with open('D:/cowboyoutfits/yolov5l6-transformer.yaml', 'w') as f:yaml.dump(model3_yaml, f, default_flow_style=True)print("successful")
所有的准备工作都完成了,就差 python trian.py啦,快去看看结果怎么样了
手敲代码300+行,觉得本文对您有帮助的话,不妨给我点个赞,如果还有哪里没看懂,可以在评论区讨论,欢迎大家踊跃发言